LLM evaluation frameworks
Automated evaluation pipelines, regression suites, and groundedness checks that make model quality measurable and every change comparable against a baseline.
- Golden datasets
- Regression testing
- LLM-as-judge, calibrated
We build the evaluation, experimentation, and iteration infrastructure that turns promising AI prototypes into reliable, grounded systems, so every change ships with evidence rather than hope.
Most AI projects stall between a convincing demo and a dependable product. We close that gap with systems for measuring quality, running disciplined experiments, and iterating safely.
Automated evaluation pipelines, regression suites, and groundedness checks that make model quality measurable and every change comparable against a baseline.
Statistically rigorous A/B testing, contextual bandits, and reproducible offline experiments, so teams can iterate quickly and know what actually moved the needle.
Multi-agent workflows that translate expert decision processes into structured, repeatable tasks. Each is designed from day one to be observable and testable step by step.
Retrieval and generation pipelines built around source fidelity: vector and hybrid search, citations users can verify, and evals that catch unsupported claims.
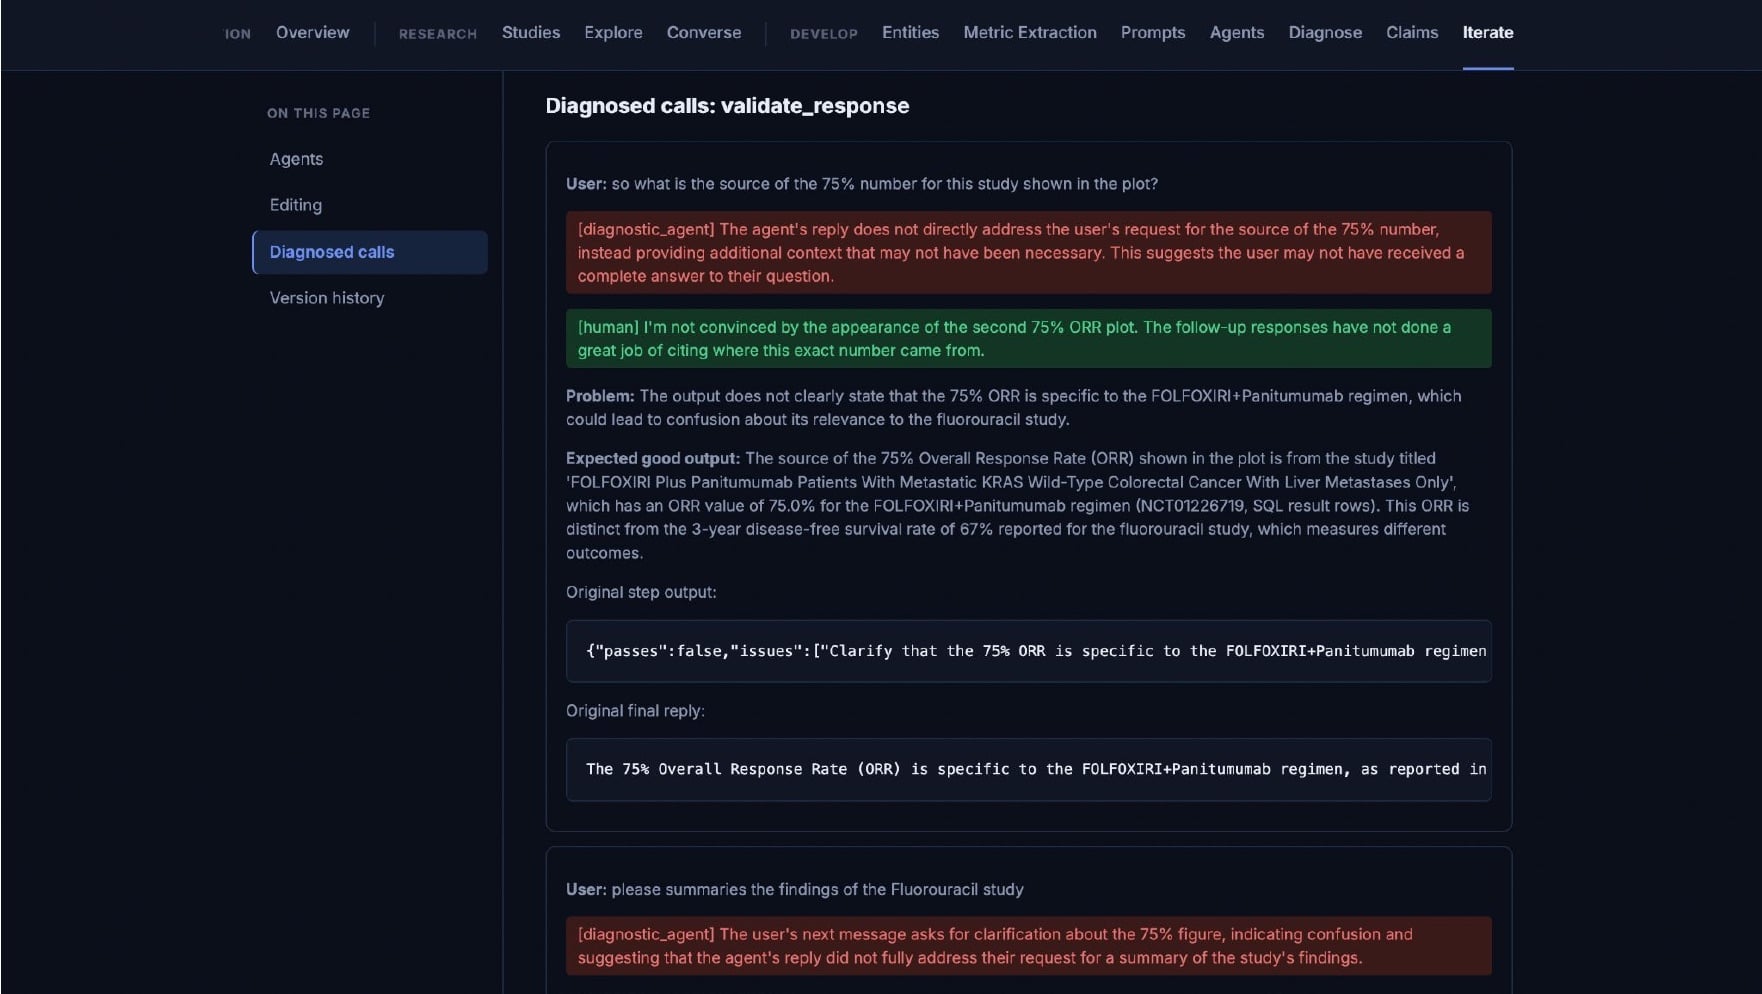
Structured workflows that capture subject-matter-expert judgement and feed it back into prompts, datasets, and models, focusing expert time where it has the most leverage.
Guardrails, policy checks, and safety assessments for applications that serve sensitive domains and potentially vulnerable users, including healthcare.
Trustworthy AI isn't a feature you add at the end. It comes from how a system is measured, tested, and governed from the very first prototype.
Behaviour you can predict and defend. Every prompt, model, or tool change is tested against the same evidence before it reaches users.
Answers anchored in your data, not the model's imagination. Outputs are traceable to sources and checked for faithfulness.
Humans stay in control where it matters. Systems are designed around the people who use them and the people they affect.
We start by defining what "good" looks like, then build the harness that lets your team improve against it continuously.
Work with your domain experts to turn fuzzy goals into concrete success criteria, failure modes, and a representative evaluation set.
Stand up automated evaluation pipelines, tracing, and regression tests so every candidate change gets an objective scorecard.
Iterate on prompts, retrieval, tools, and models with disciplined offline and online experiments, and ship only what the evidence supports.
Route uncertain cases to experts, fold their feedback back into datasets and evals, and keep quality improving after launch.
The result is a repeatable loop your team owns, not a one-off model drop.
Our own platforms put these principles into practice: grounded outputs, traceable agents, and improvement loops driven by expert input. Get in touch to request a demo or access.
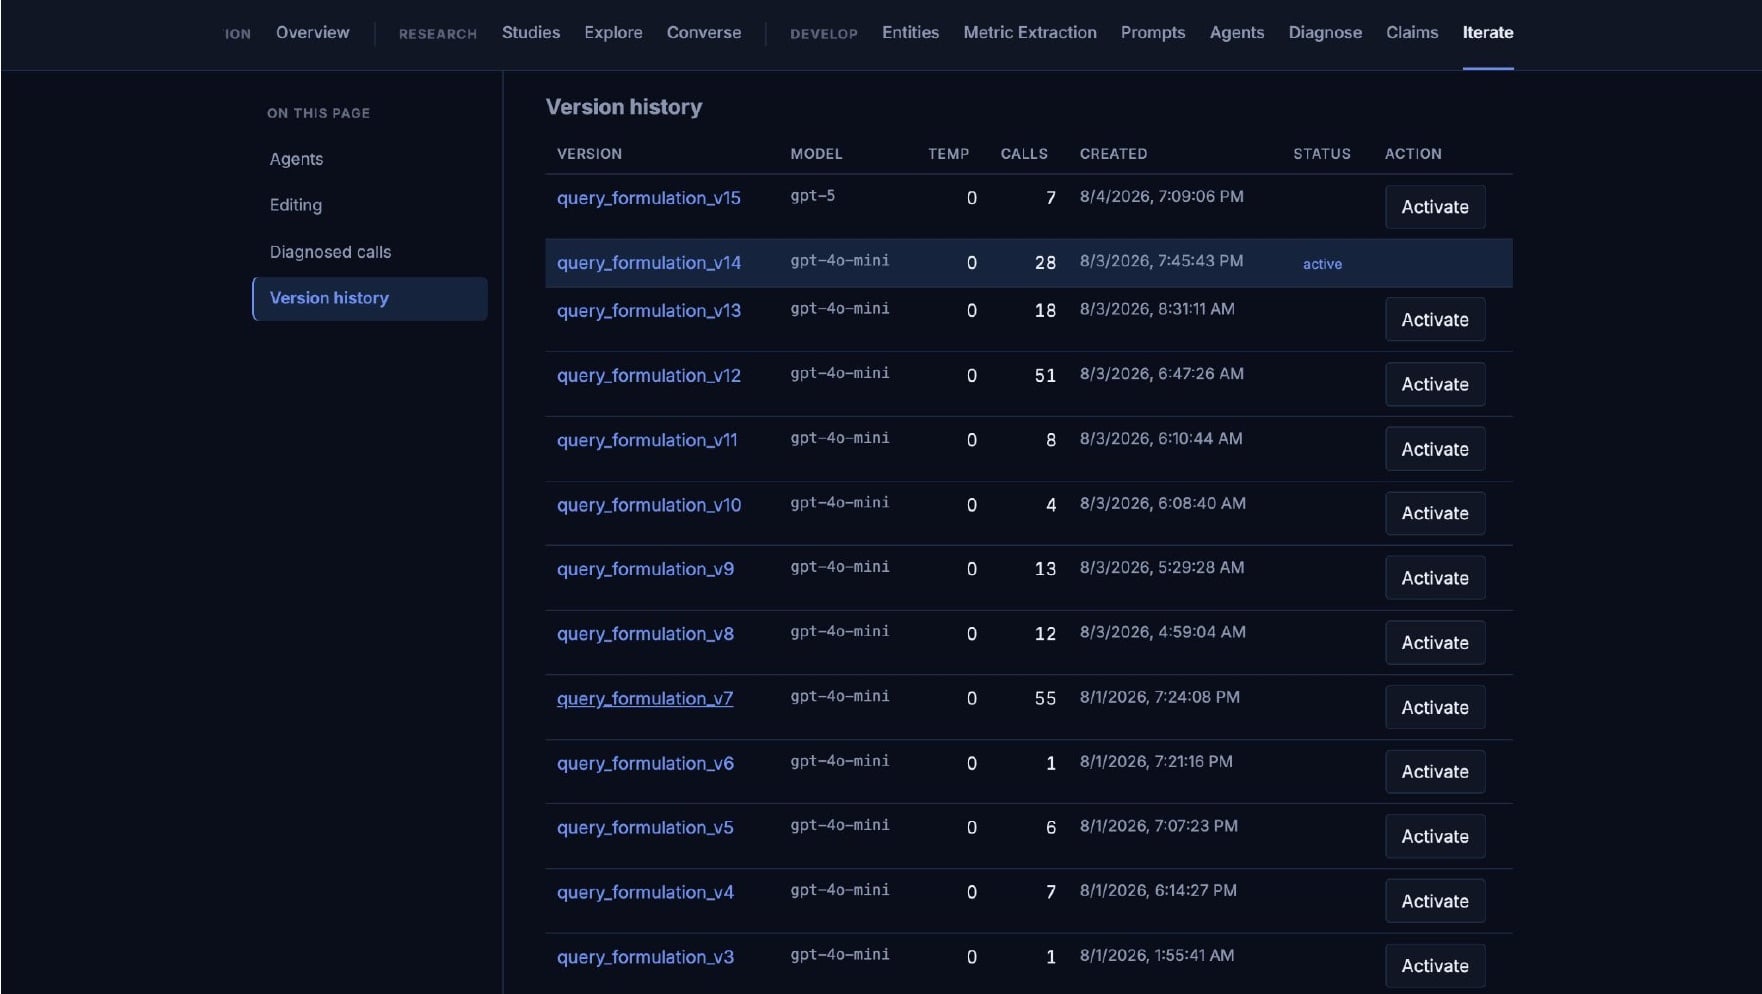
A responsible, grounded multi-agent platform that helps domain experts reason across more evidence than any individual could review, and gets measurably better every time an expert weighs in.
Built for clinical researchers asking where the most promising, underexplored therapeutic opportunities lie, using public trial registries and published literature.
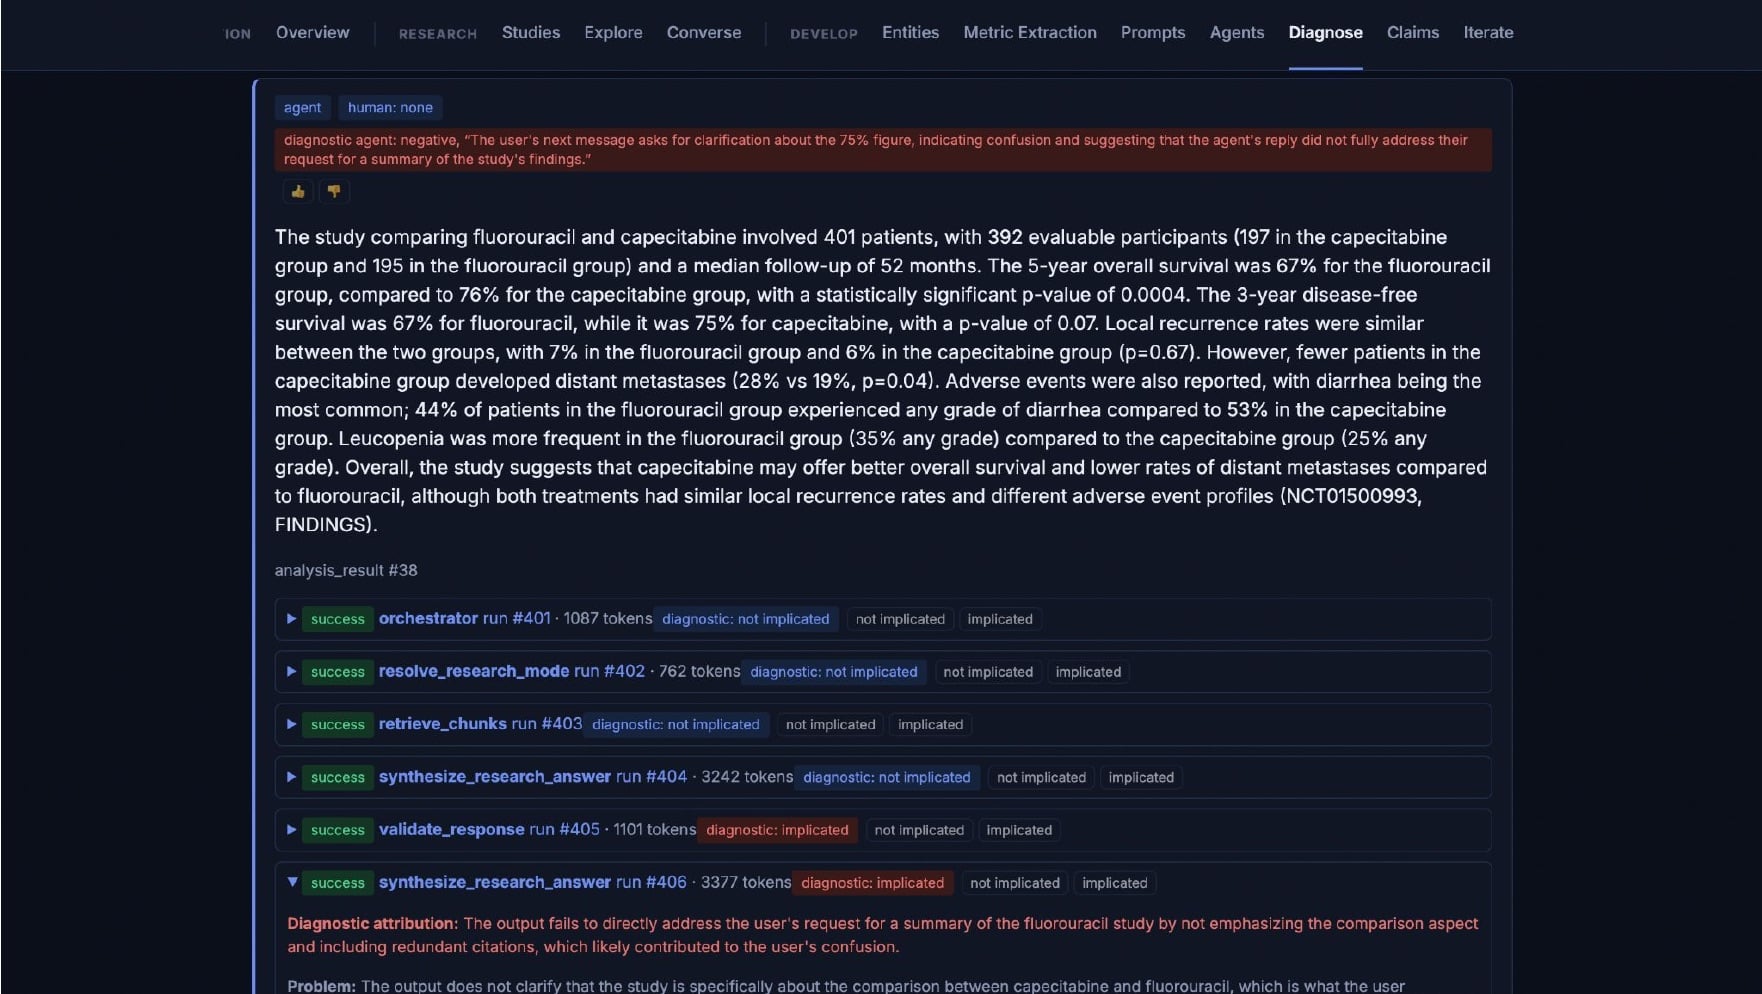
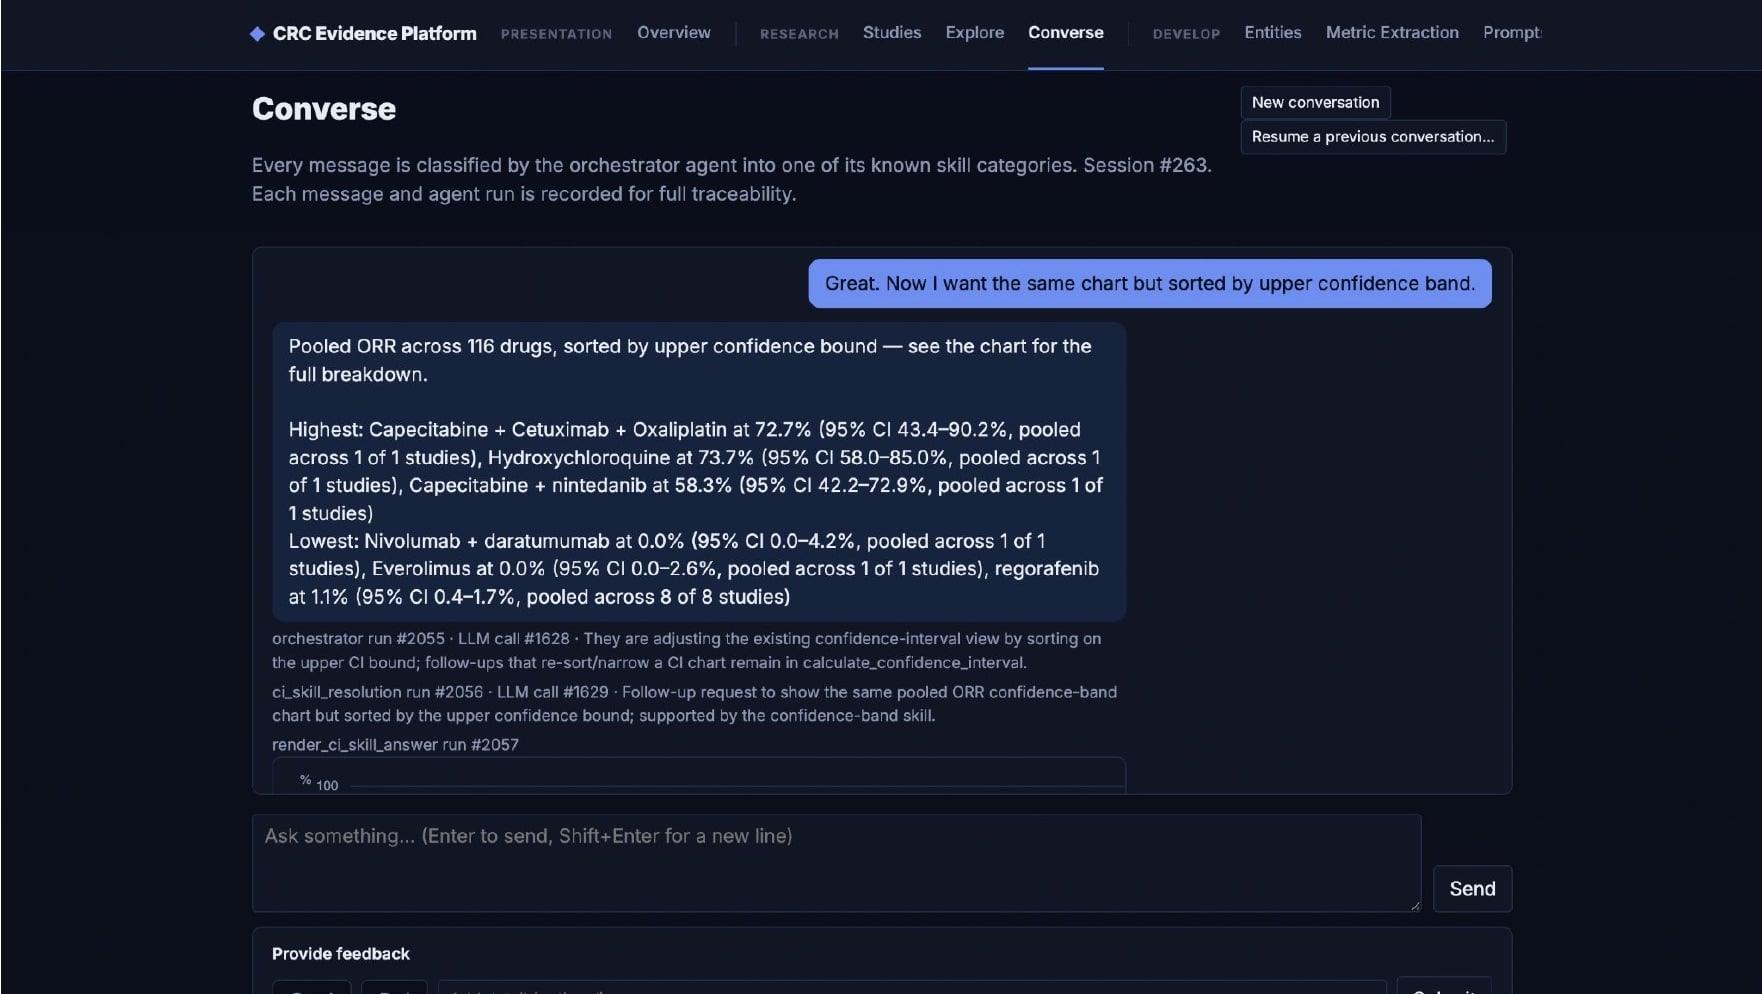
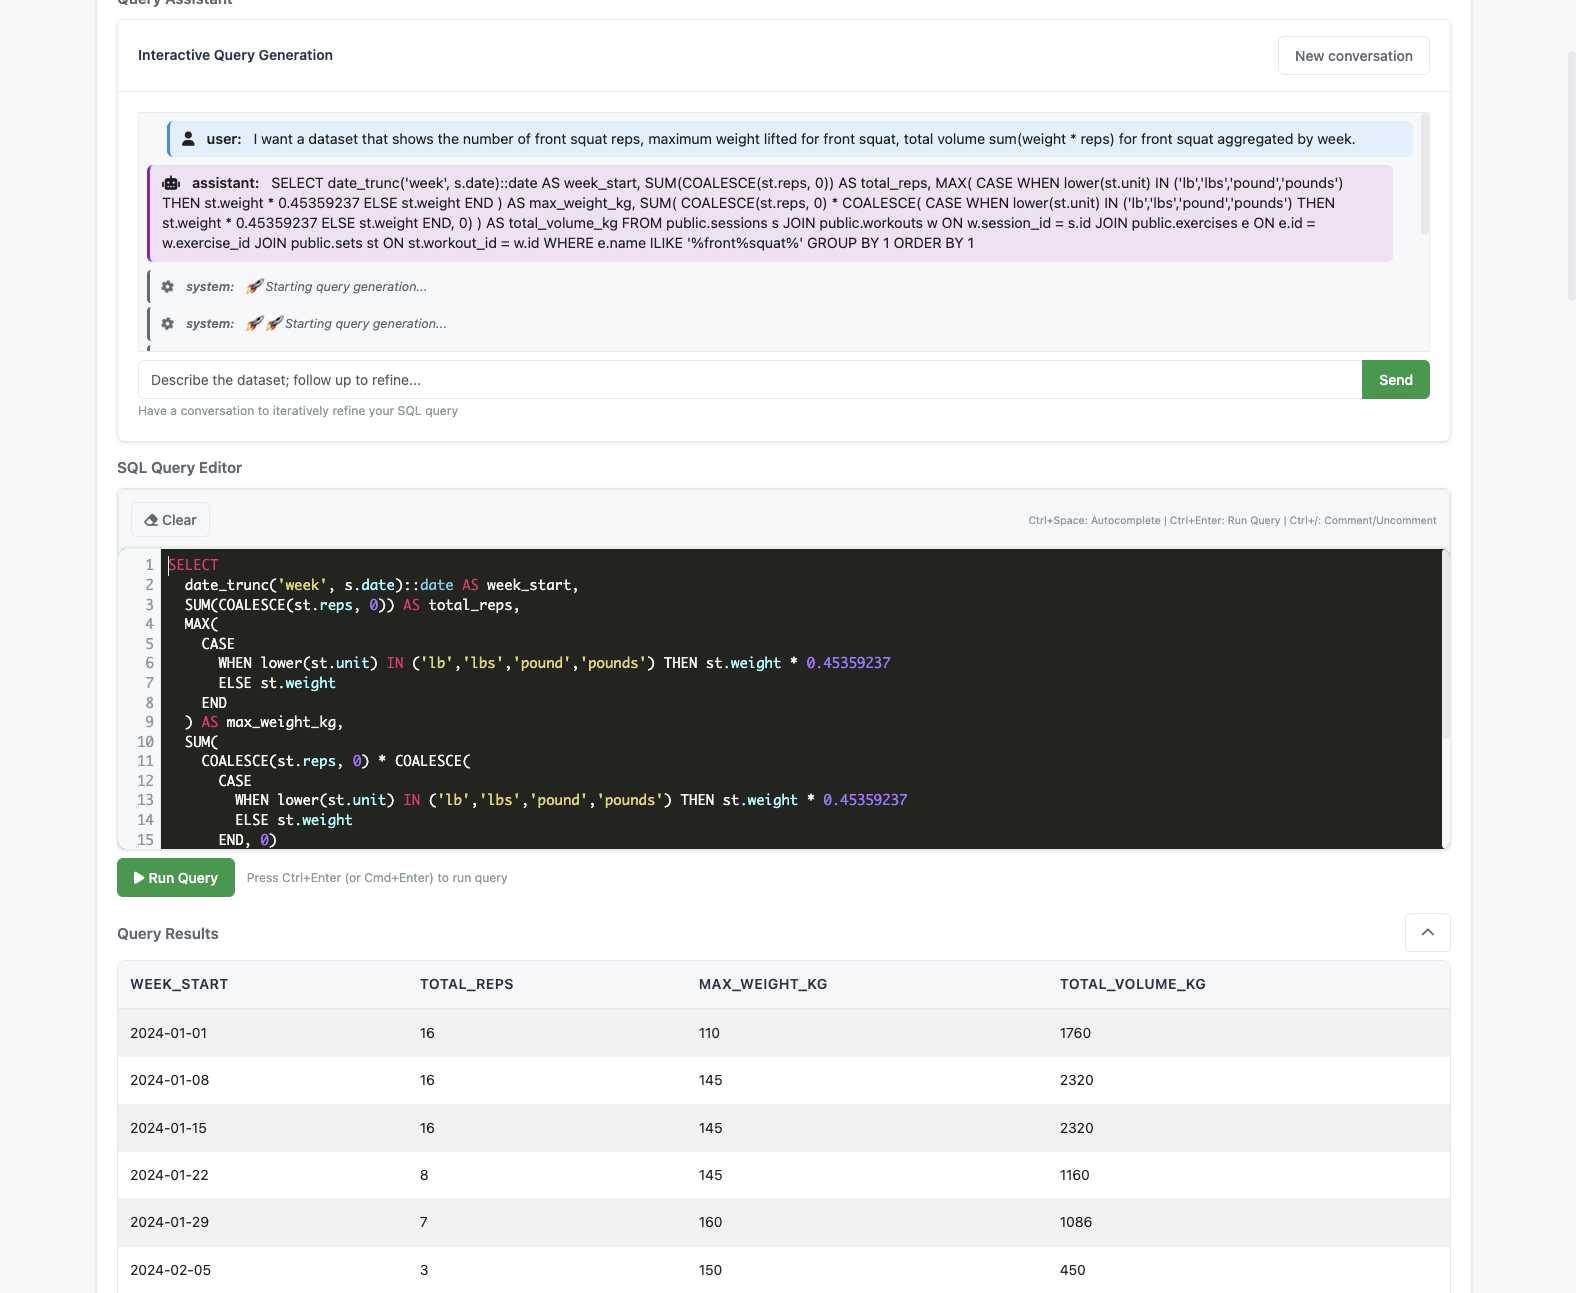
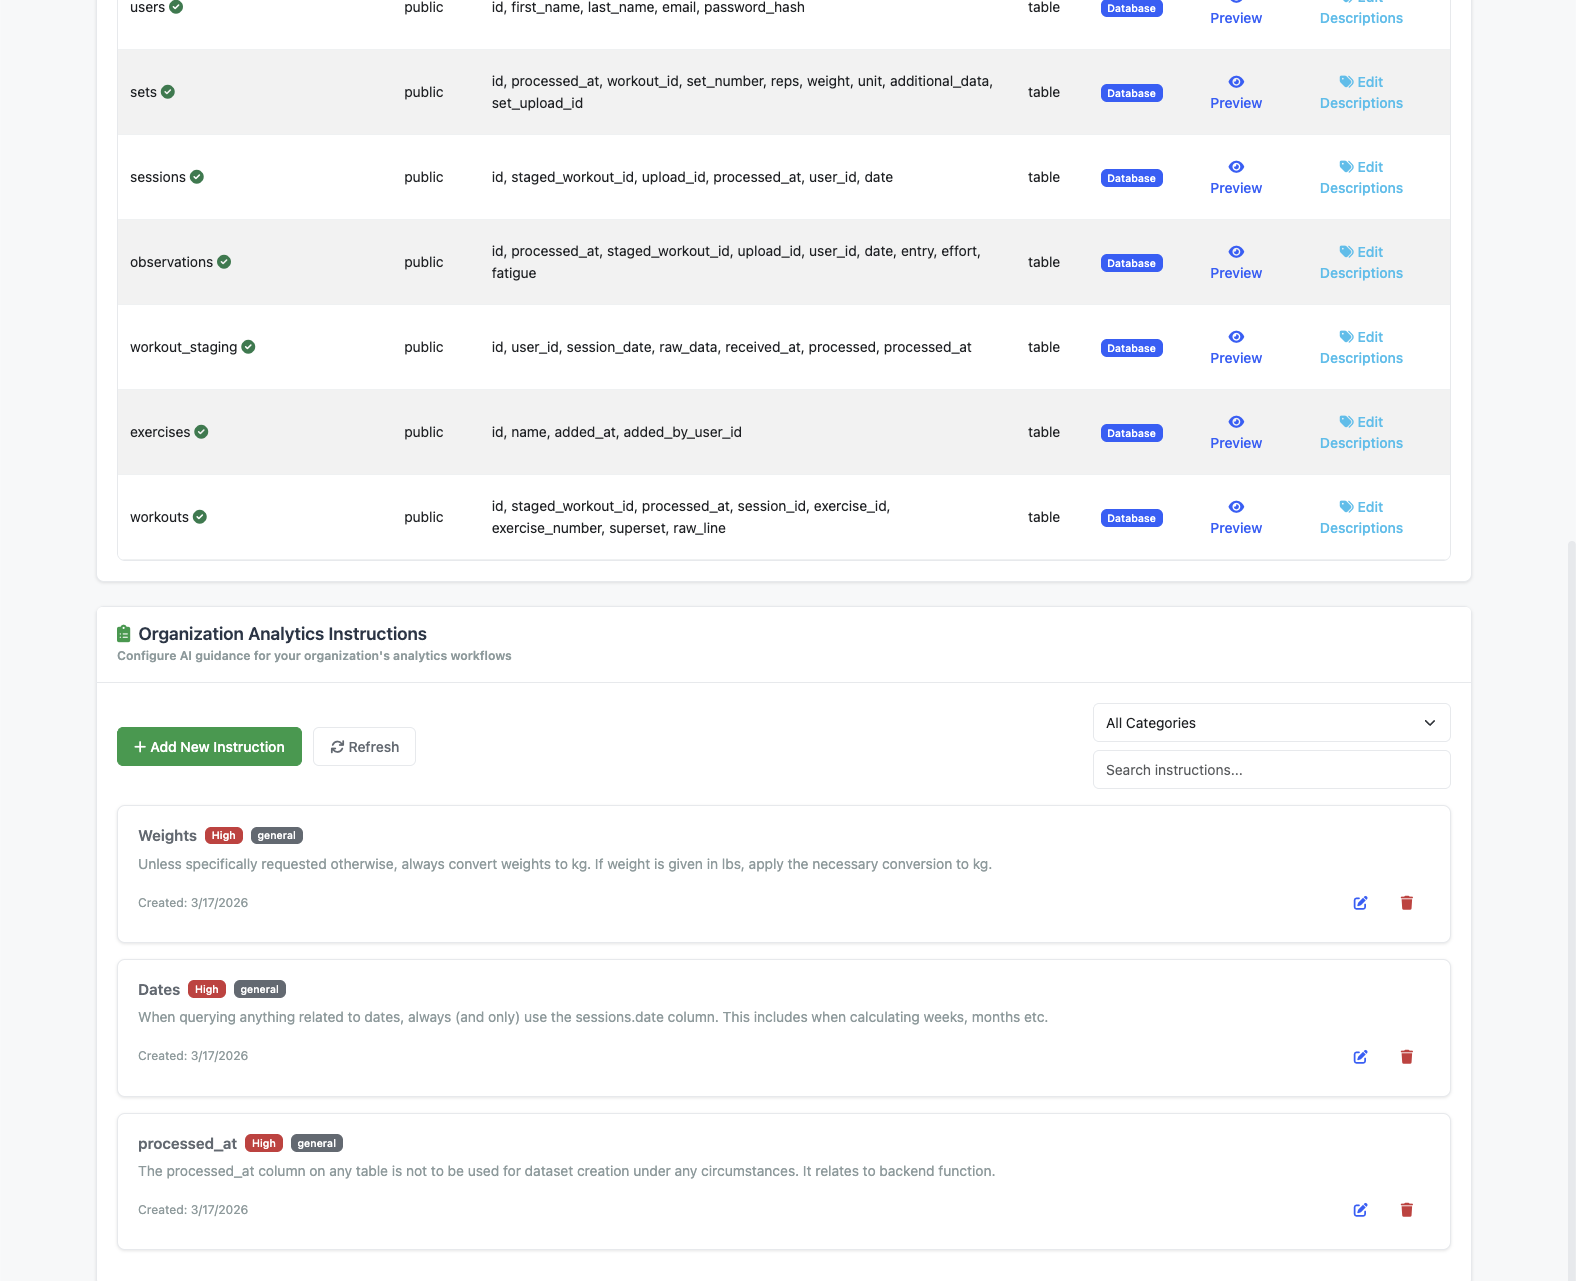
Lets people ask questions of their data in plain language and get answers that stay faithful to it.
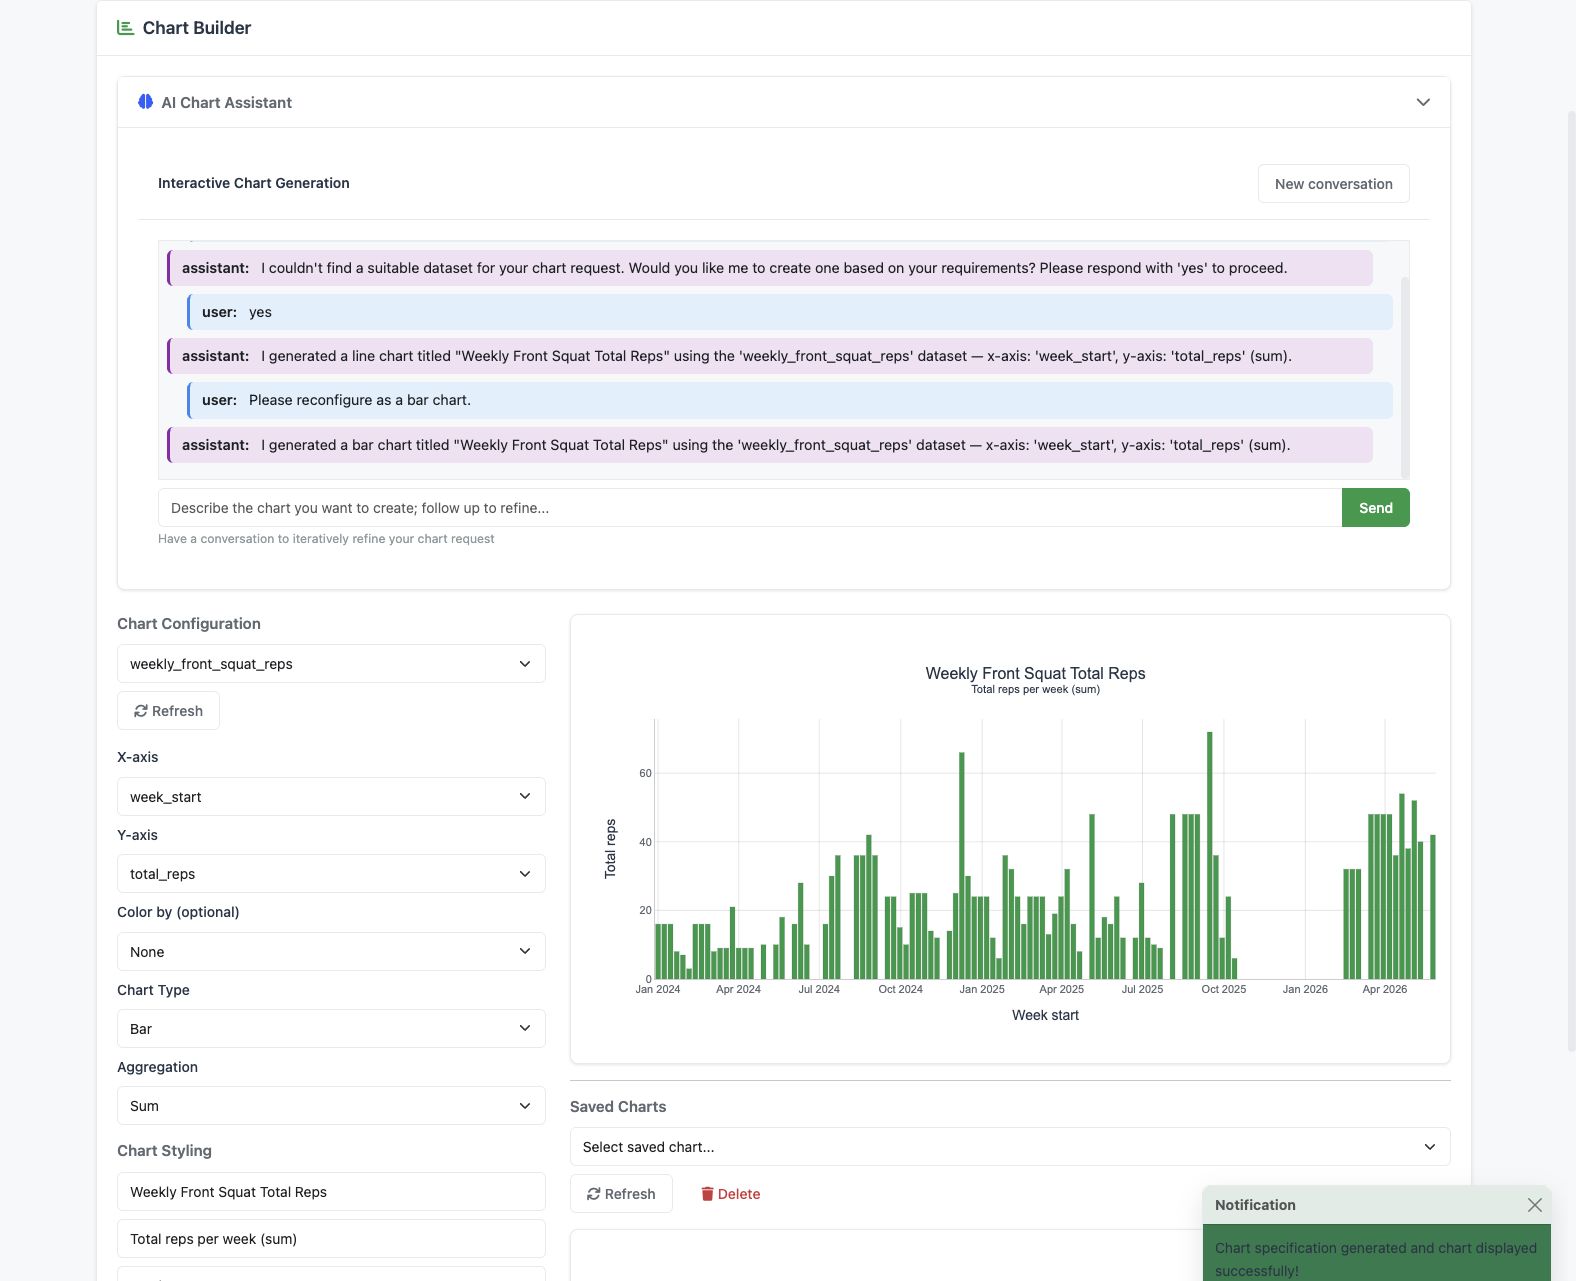
Multi-modal search that brings audio archives to life, with answers users can verify.
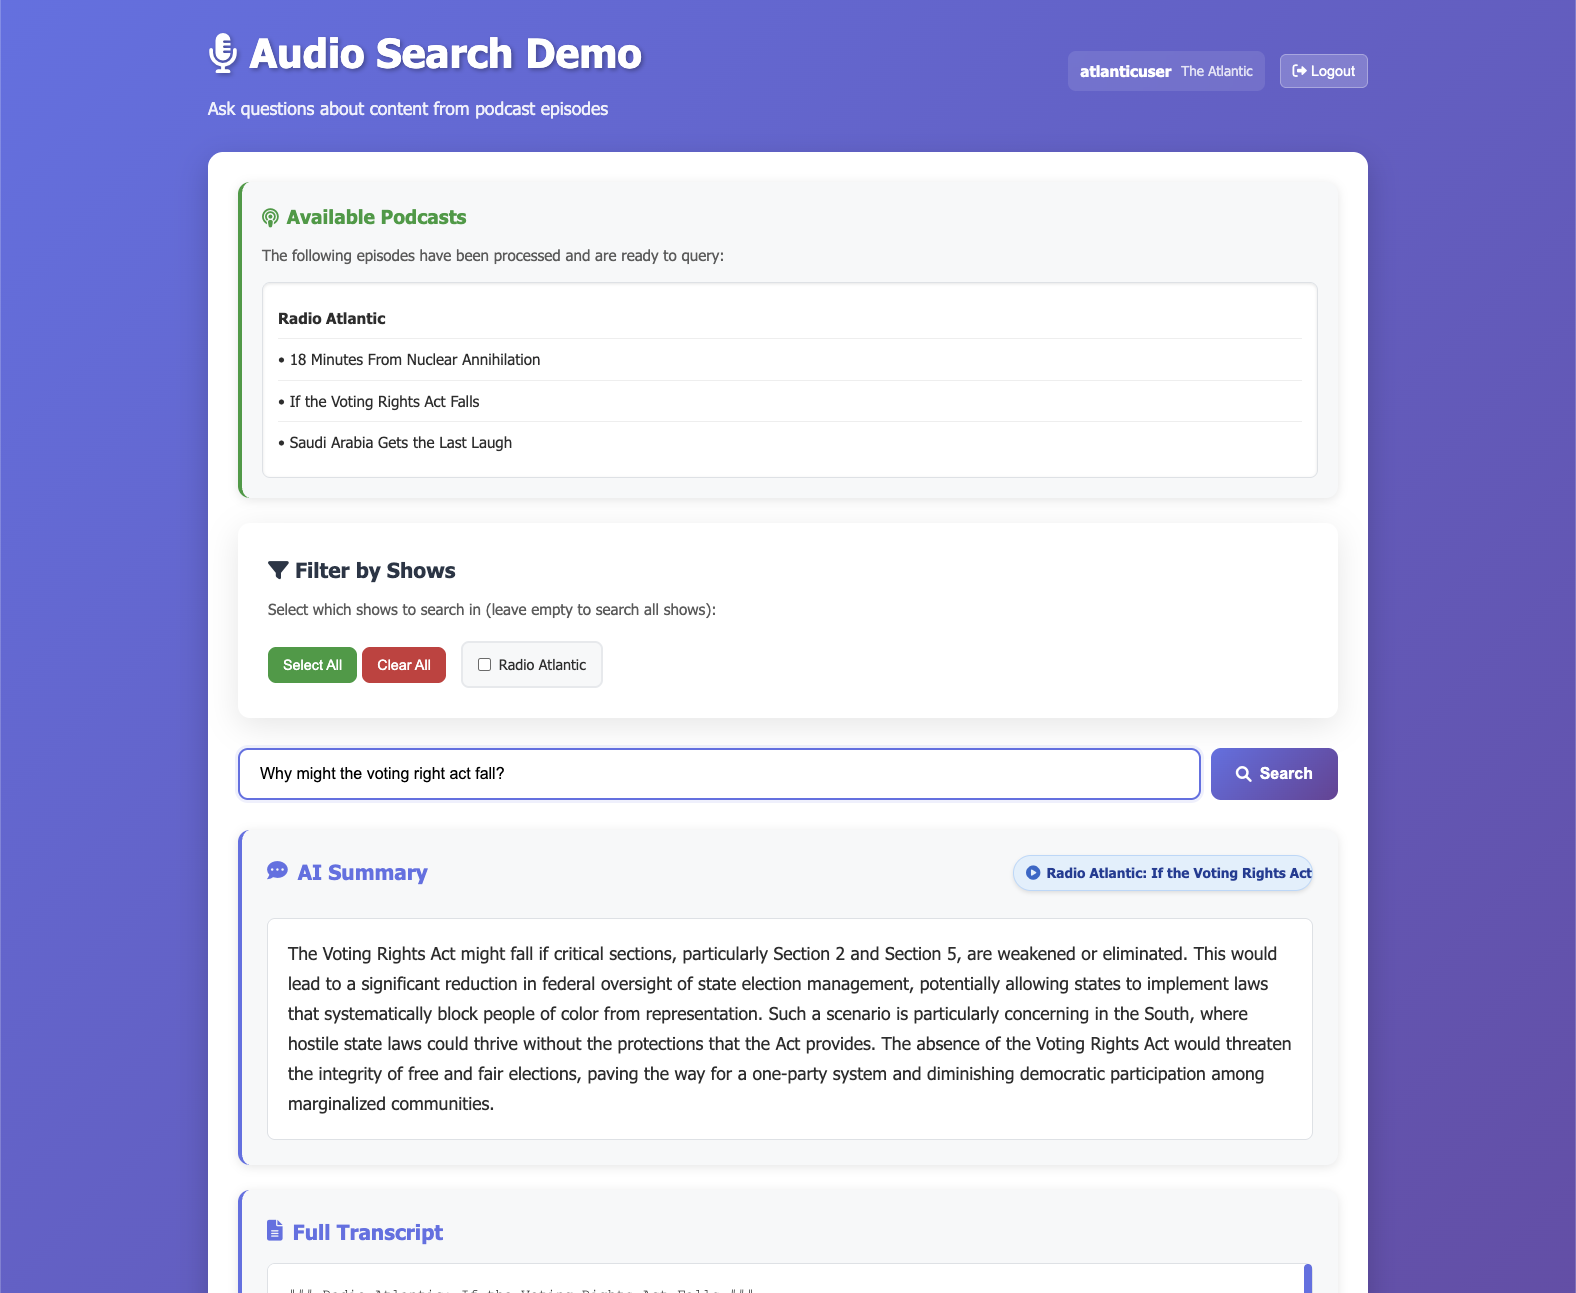
Machine learning at the press of a button, with expert feedback built into the loop.
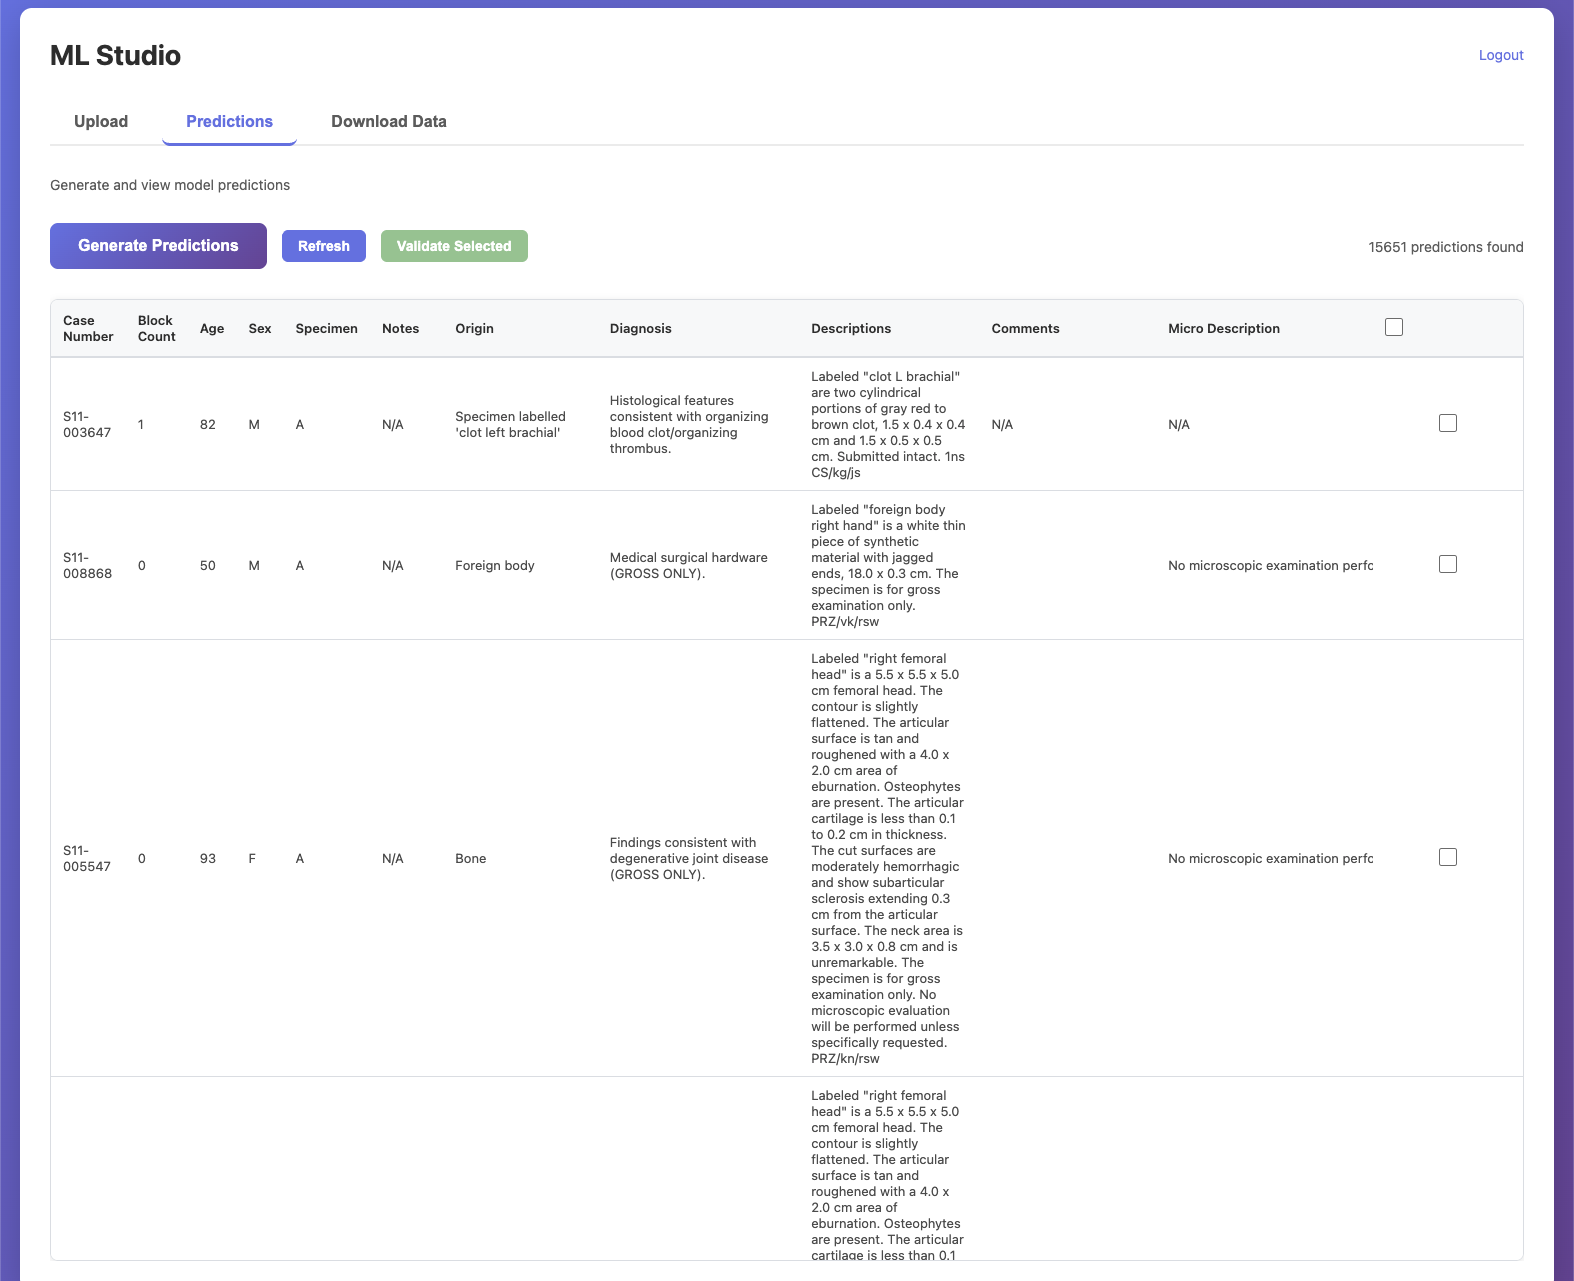
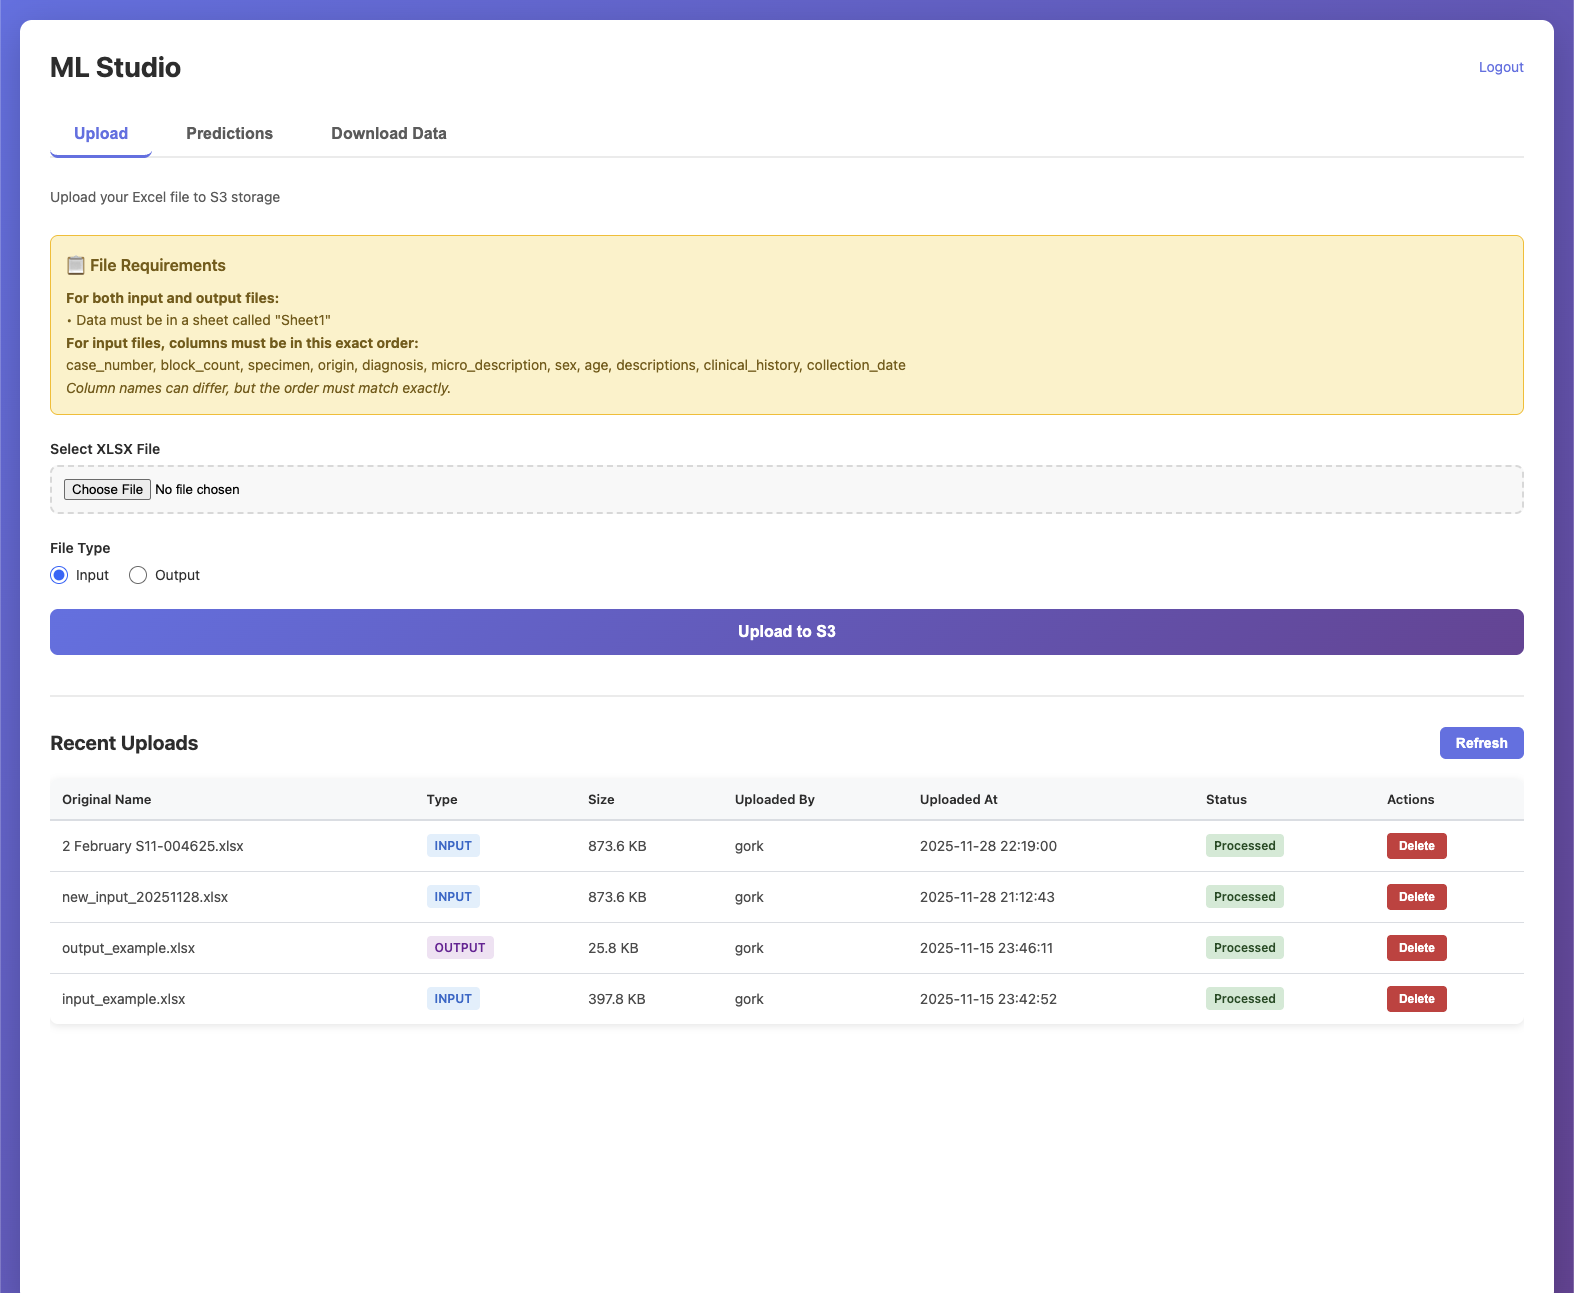
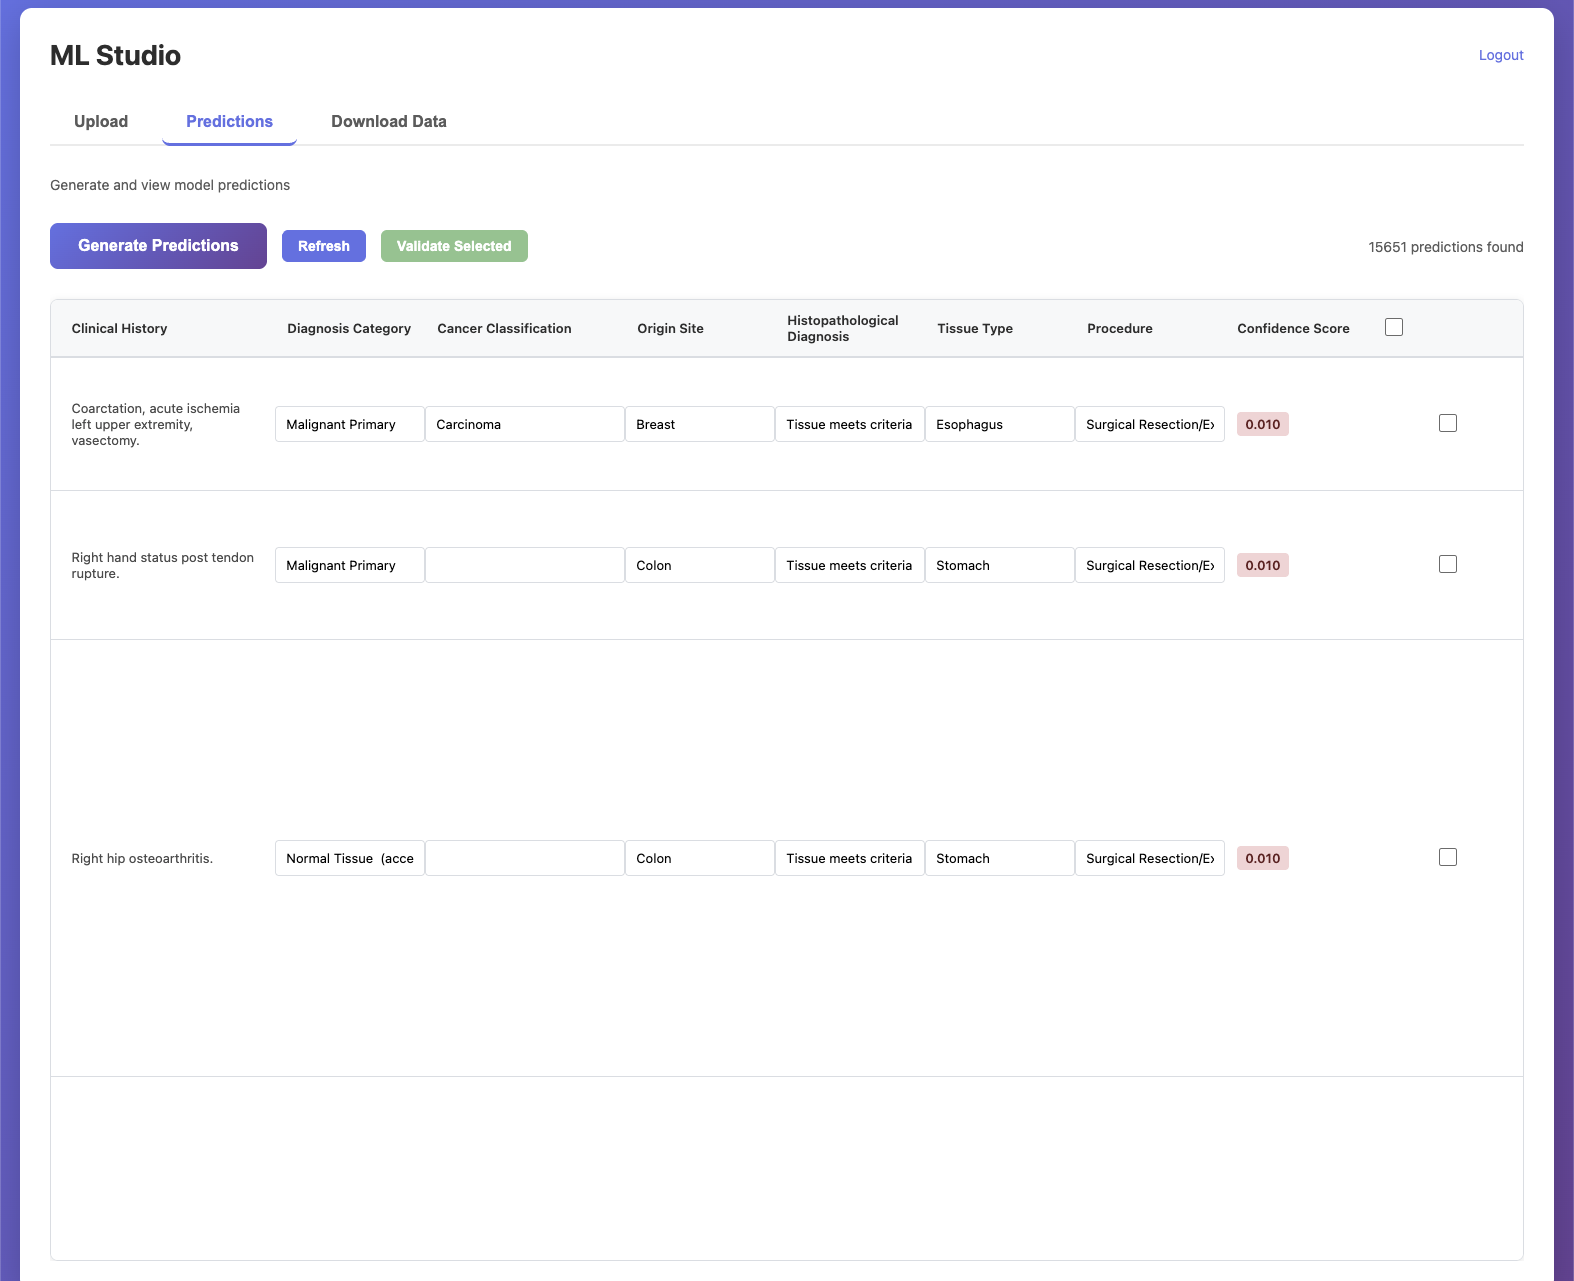
We also design and ship our own iOS apps as a proving ground for the same craft, data-informed iteration, and care for users.
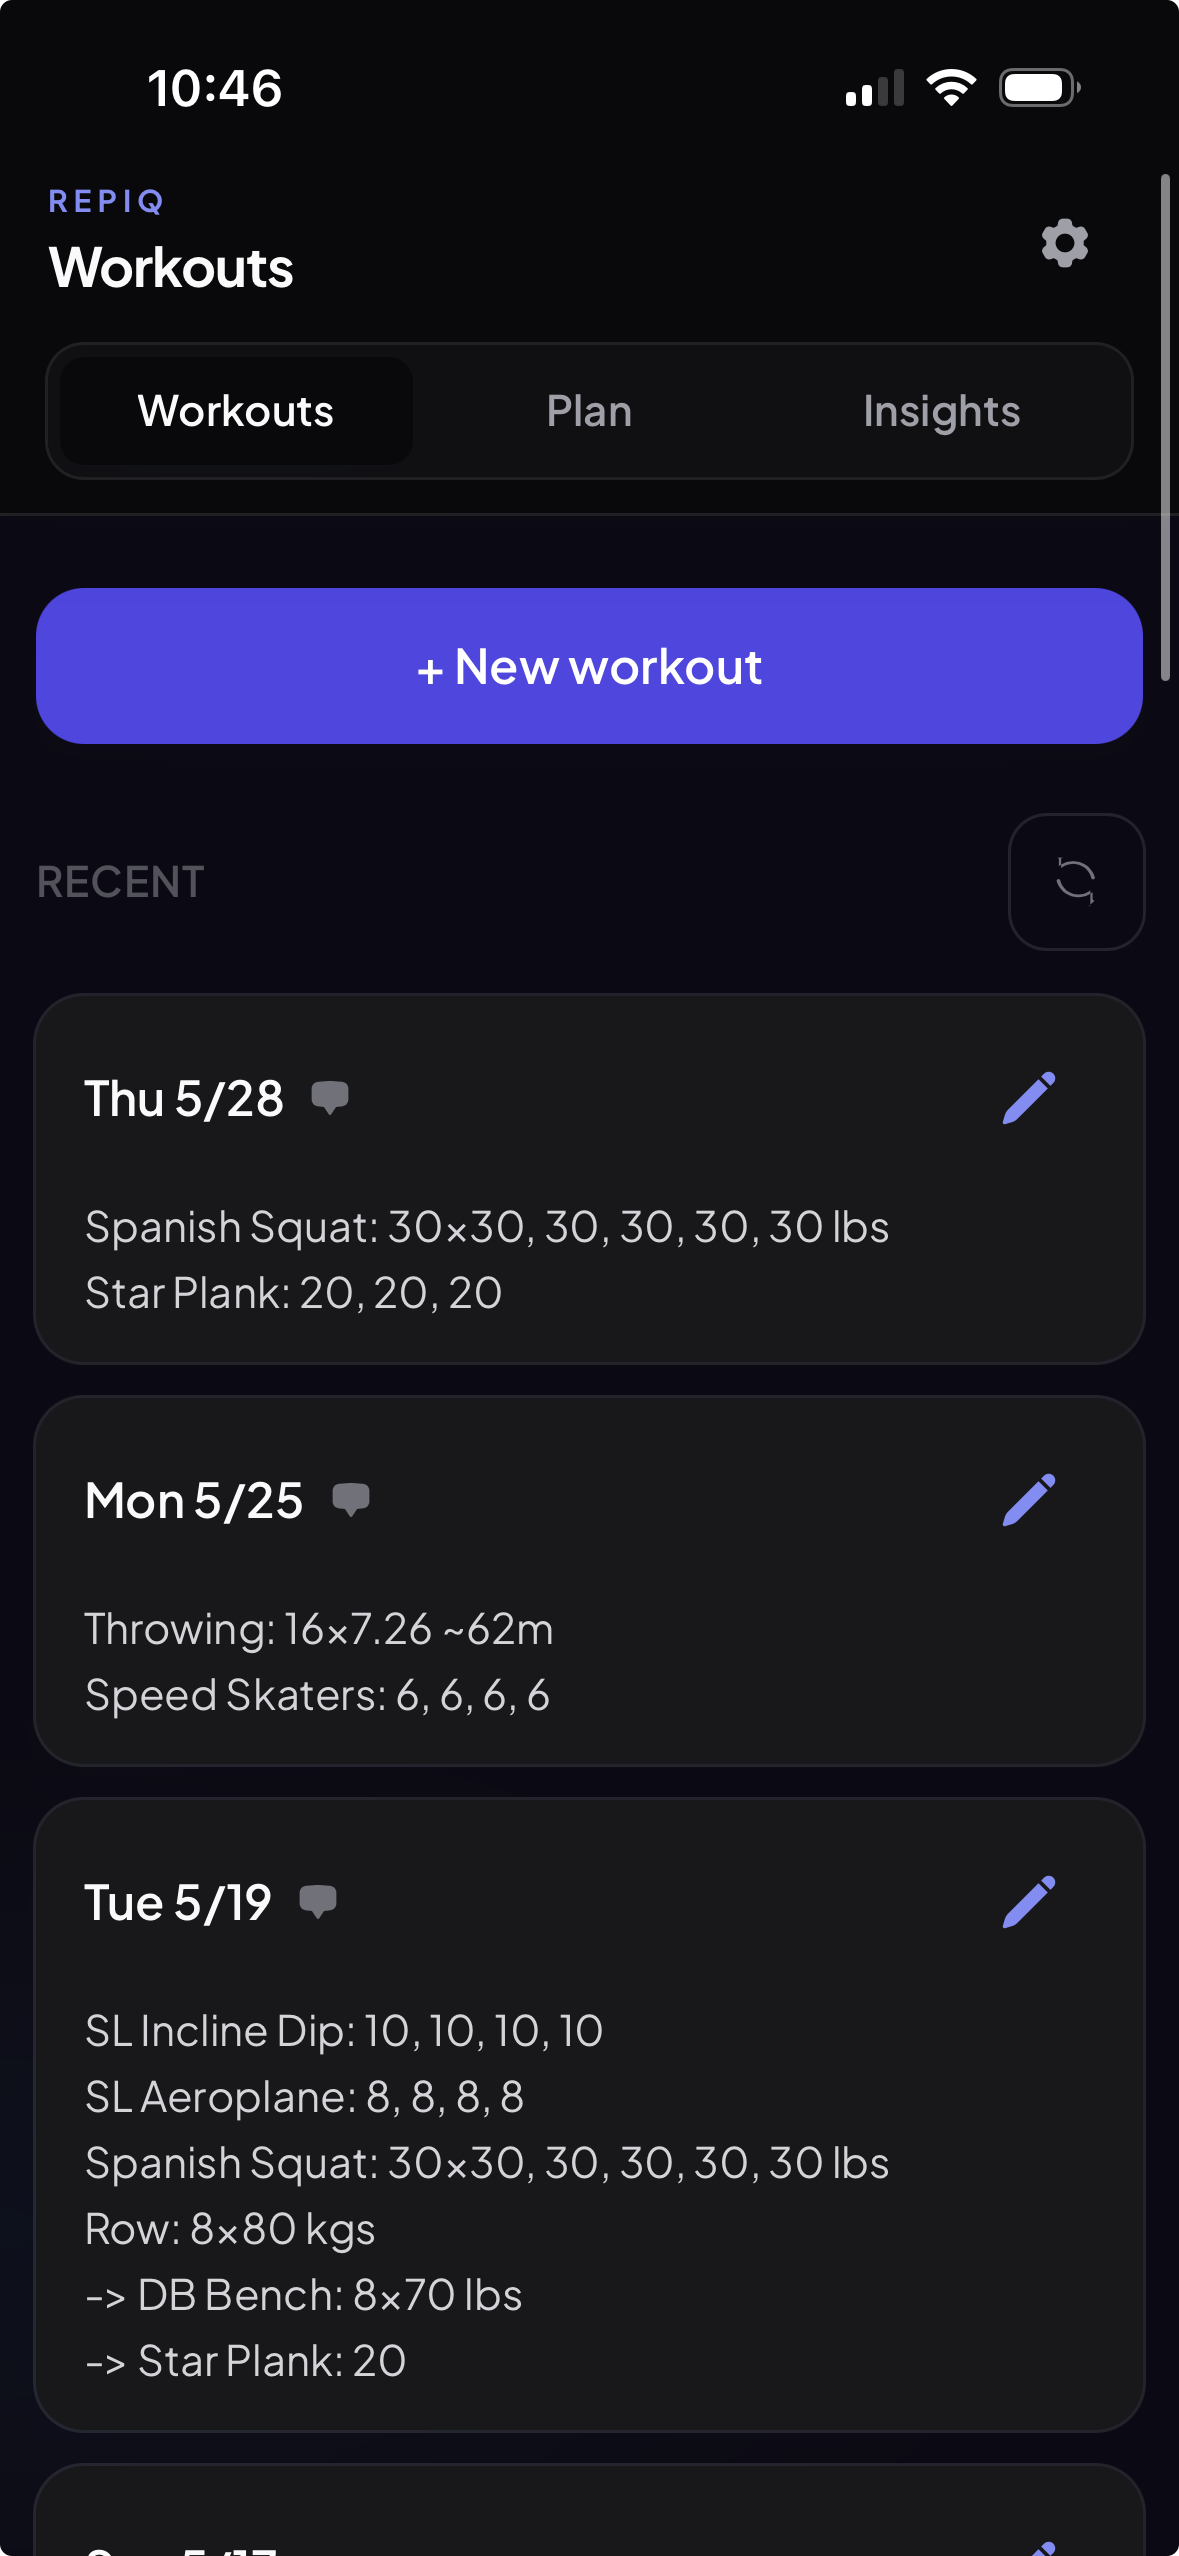

Tailored training plans, intelligent charts, and AI-assisted insight into fatigue and effort, with coach collaboration built in.


A chore and reminder tracker for households. Schedule tasks, get reminded, and divide and conquer.
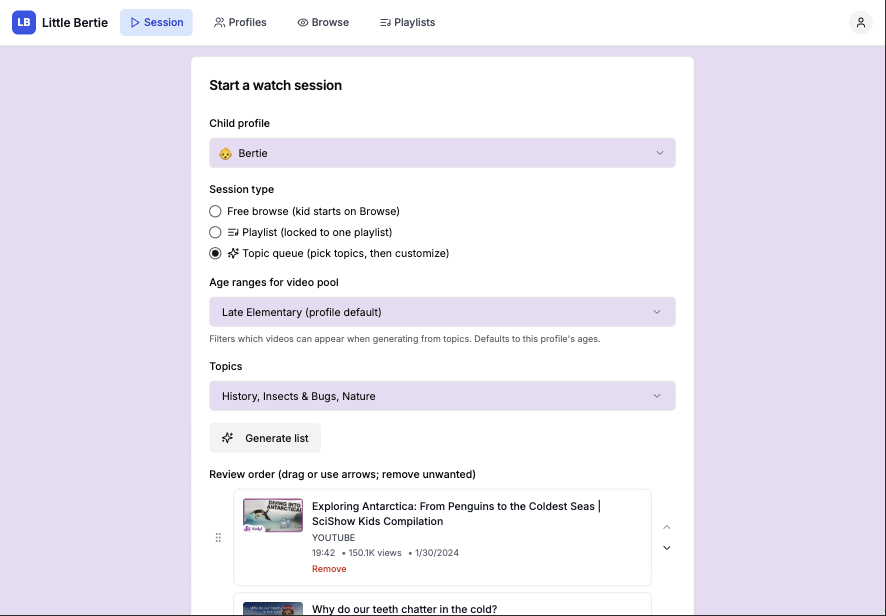
Safe, wholesome screen time: quality YouTube content without AI slop or predatory algorithms.


Checkers meets football. Position your players and aim your kicks against a friend or a smart AI.
Available on iOS. Email admin@prismaticinsights.ai to join user testing.
Prismatic Insights is an independent applied AI practice. We work hands-on, building production ML systems, evaluation frameworks, and experimentation infrastructure alongside the teams who will own them.
Our work spans sensitive domains, consumer products, and enterprise data: from multi-agent systems that turn expert decision processes into repeatable workflows, to retrieval systems built for grounded, trustworthy generation.
We care as much about how a system is measured as how it is built. That means clear success criteria, honest evaluation, and safety guardrails proportionate to the people a product serves.
Whether you're evaluating an agent before launch, building experimentation infrastructure, or grounding an assistant in your own data, let's talk about what reliable looks like for you.